Output outran review
Engines ship enormous volume fast. Human review capacity did not grow at the same rate, so off-brand and translated-sounding lines slip through unread.
Still Needs a Human is an independent quality layer for AI and machine translation, built by people who ran localization quality for a living. We do not sell you the translation, so our verdict has no reason to flatter any engine or any vendor.
AI and machine translation now produce more words in a day than a team could once review in a month. The mechanical checkers kept counting tags and numbers. Nobody built the layer that judges whether the copy reads like a person wrote it, and nobody wanted to put their name on the answer.
Engines ship enormous volume fast. Human review capacity did not grow at the same rate, so off-brand and translated-sounding lines slip through unread.
Tag, number and terminology checkers pass copy that reads flat and off tone. They were never built to judge naturalness or brand voice.
A model alone is confident and sometimes wrong. For anything a client sees, someone still has to make the final call and stand behind it.
This is not a wrapper around a language model. It is the accumulated craft of running quality on real deliveries, turned into a system that checks the things reviewers actually argue about. The judgement is ours. The scale is the software's.
Reading real deliveries, catching what the mechanical checkers miss and separating the certain issues from the ones that need a human eye. That split is now the engine's two layers.
Defensible scoring against MQM and DQF-style templates, with categories, severities and weights a client and a vendor can both live with, which is why templates in the product are yours to rename and re-weight.
Knowing when a line is correct but off brand and what a native, on-voice rewrite should read like. That judgement became its own scorecard rather than a hidden tone model.
Comparing engines and models on the same source against a human reference, so the engine decision rests on evidence rather than vendor claims, including the rule that a model never grades its own output.
Everything in the product follows from the same three commitments. They are why the name is the promise.
AI reads everything and proposes. A person confirms or overrides, and the correction is made in your own tool. We never overwrite your file, and the machine never has the last word on its own.
We grade the machines; we are not one of them. We do not sell translation, resell engines or take a cut of a vendor's margin.
Real issues with the evidence and a suggested fix, not a vanity score. When the second model cannot tell, it says so instead of inventing certainty.
Still Needs a Human is run by the two people who built it. We came out of production localization work: reading real deliveries, arguing about severity levels and explaining to a client why a technically correct line was still wrong. The product is that argument, made repeatable.
Human review is done by named linguists working under NDA in the locales they live in. You see who reviewed your delivery, on the report.
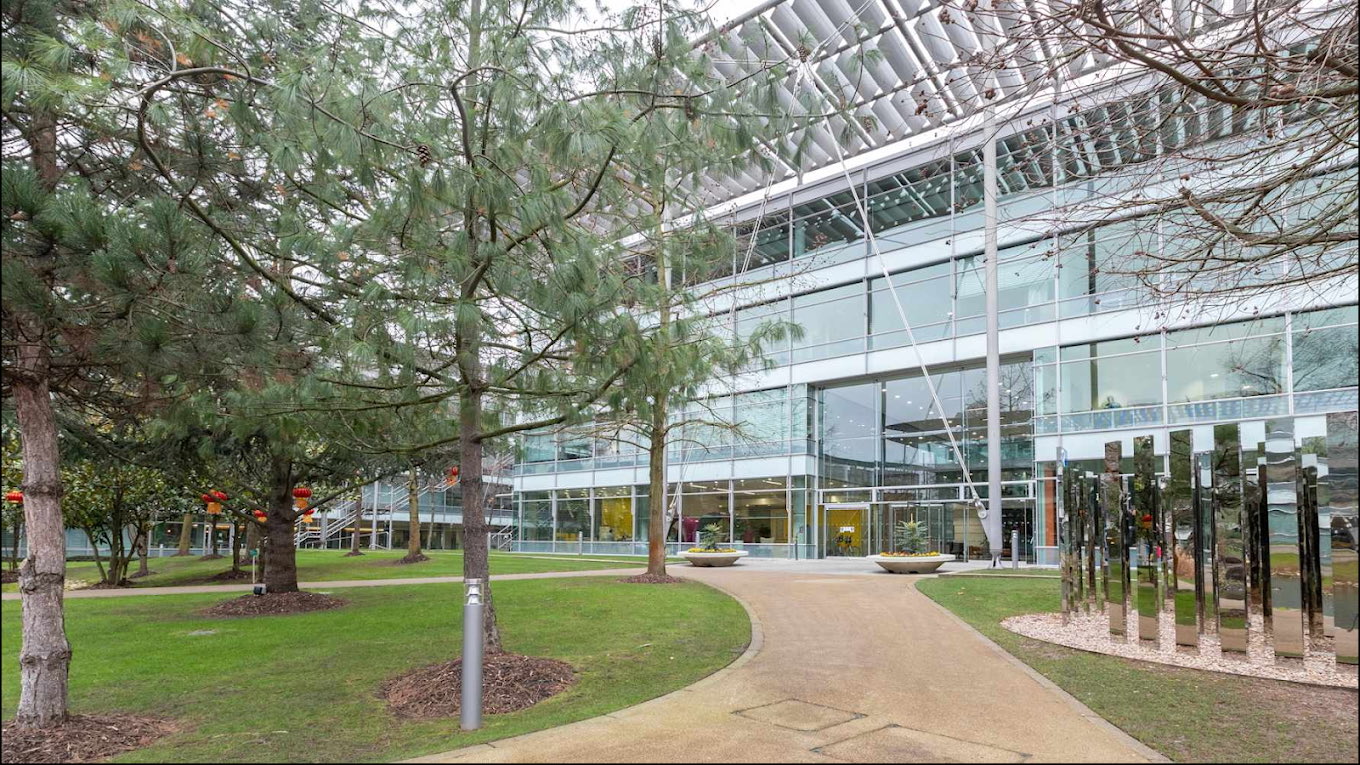
Our home is Building 3 in Chiswick Park, the lakeside campus on Chiswick High Road built around water, green space and the people who work there. It suits a company whose whole point is keeping the human in the picture.
We will run it, show you what your current check missed and hand you the report. No migration, no integration, no long procurement to see whether it works.